diff --git a/README.md b/README.md
index 5ae7357..6823835 100644
--- a/README.md
+++ b/README.md
@@ -1,17 +1,17 @@
# ComfyUI-MultiGPU v2: Universal .safetensors and GGUF Multi-GPU Distribution with DisTorch
+
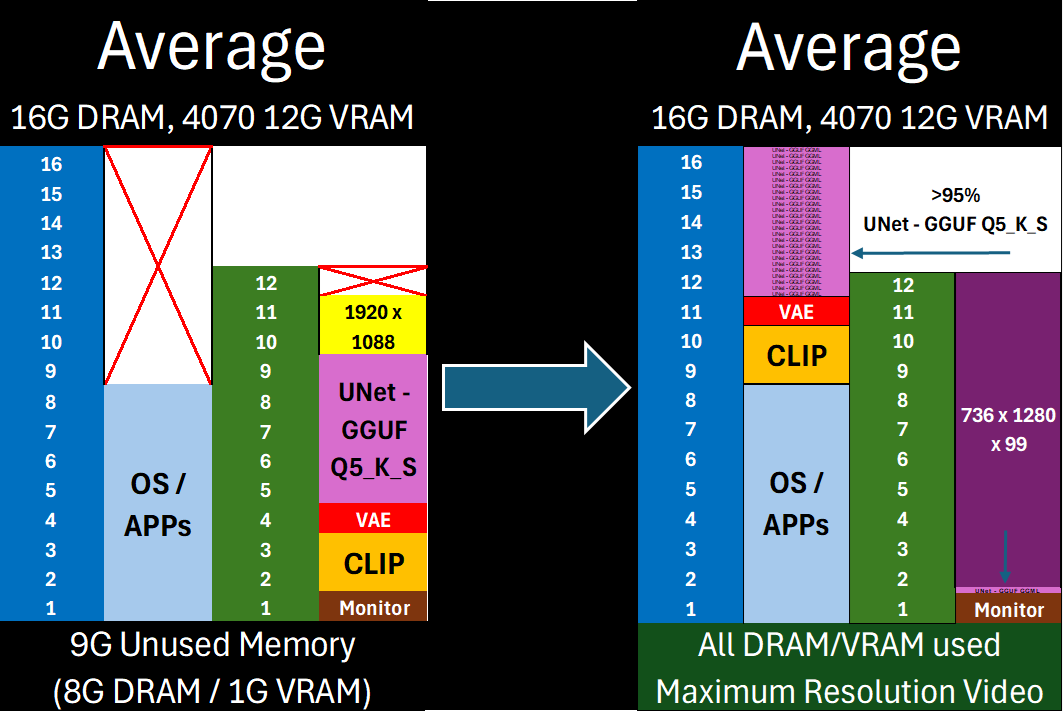
Free almost all of your GPU for what matters: Maximum latent space processing
-## The Core of ComfyUI-MultiGPU v2:
-[^1]: This **enhances memory management,** not parallel processing. Workflow steps still execute sequentially, but with components (in full or in part) loaded across your specified devices. *Performance gains* come from avoiding repeated model loading/unloading when VRAM is constrained. *Capability gains* come from offloading as much of the model (VAE/CLIP/UNet) off of your main **compute** device as possible—allowing you to maximize latent space for actual computation.
+## The Core of ComfyUI-MultiGPU v2
-1. **Universal .safetensors Support**: Native DisTorch2 distribution for all `.safetensors` models.
-2. **Up to 10% Faster GGUF Inference versus DisTorch1**: The new DisTorch2 logic provides potential speedups for GGUF models versus the DisTorch V1 method.
-3. **Bespoke WanVideoWrapper Integration**: Tightly integrated, stable support for WanVideoWrapper with eight bespoke MultiGPU nodes.
-4. **New Model-Driven Allocation Options**: Two new inutuitive model-driven Expert Modes to facilitate exact placement on all available devices - 'bytes' and 'ratio'
+1. **Universal .safetensors Support**: Native DisTorch2 distribution for all `.safetensors` models.
+2. **Up to 10% Faster GGUF Inference versus DisTorch1**: The new DisTorch2 logic provides potential speedups for GGUF models versus the DisTorch V1 method.
+3. **Bespoke WanVideoWrapper Integration**: Tightly integrated, stable support for WanVideoWrapper with eight bespoke MultiGPU nodes.
+4. **New Model-Driven Allocation Options**: Two new inutuitive model-driven Expert Modes to facilitate exact placement on all available devices - 'bytes' and 'ratio'
DisTorch: How It Works
@@ -37,11 +37,12 @@ What is DisTorch? Standing for "distributed torch", the DisTorch nodes in this c
- **Example**: `cuda:0,0.0207;cuda:1,0.1273;cpu,0.0808` will use 2.1% of `cuda:0`'s VRAM, 12.7% of `cuda:1`'s VRAM, and 8.1% of the `cpu`'s RAM to hold the model.
## 🎯 Key Benefits
+
- Free up GPU VRAM instantly without complex settings
- Run larger models by offloading layers to other system RAM
- Use all your main GPU's VRAM for actual `compute` / latent processing, or fill it up just enough to suit your needs and the remaining with quick-access model blocks.
- Seamlessly distribute .safetensors and GGUF layers across multiple GPUs if available
-- Allows **you** to easily shift from ___on-device speed___ to ___open-device latent space capability___ with a simple one-number change
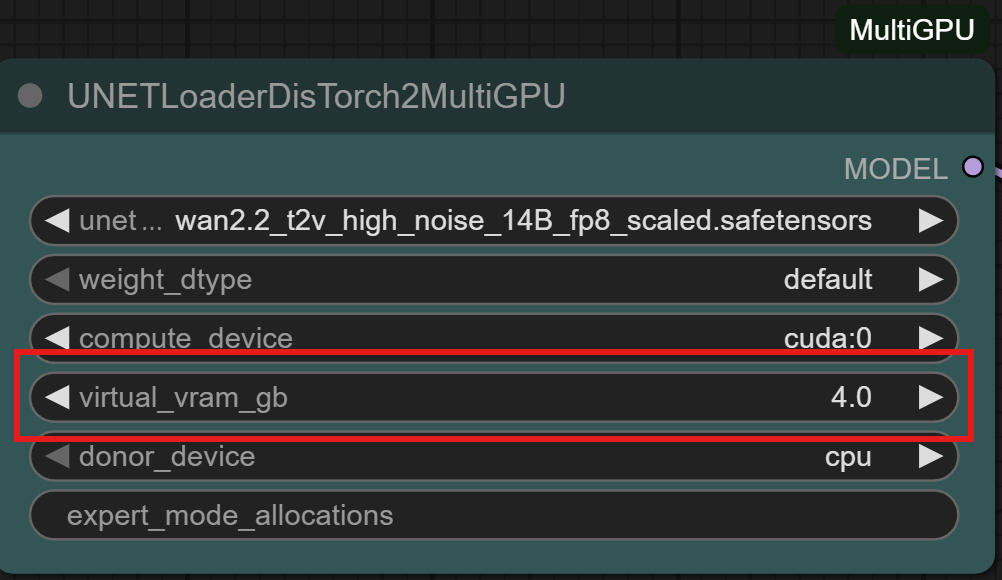
+- Allows **you** to easily shift from ***on-device speed*** to ***open-device latent space capability*** with a simple one-number change
 @@ -50,6 +51,7 @@ What is DisTorch? Standing for "distributed torch", the DisTorch nodes in this c
## 🚀 Compatibility
+
Works with all .safetensors and GGUF-quantized models.
On current ComfyUI builds with DynamicVRAM/comfy-aimdo enabled, MultiGPU keeps DynamicVRAM active on CUDA devices that comfy-aimdo has initialized and falls back to legacy model patching for off-grid MultiGPU CUDA devices. This preserves MultiGPU placement for devices such as `cuda:1` even when comfy-aimdo only initialized the primary device.
@@ -110,7 +112,7 @@ Currently supported nodes (automatically detected if available):
- [LoadWanVideoClipTextEncoderMultiGPU](web/docs/LoadWanVideoClipTextEncoderMultiGPU.md)
- [FantasyTalkingModelLoaderMultiGPU](web/docs/FantasyTalkingModelLoaderMultiGPU.md)
- [Wav2VecModelLoaderMultiGPU](web/docs/Wav2VecModelLoaderMultiGPU.md) / [DownloadAndLoadWav2VecModelMultiGPU](web/docs/DownloadAndLoadWav2VecModelMultiGPU.md)
-- GGUF loaders (requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF)):
+- GGUF loaders (requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF) or [ComfyUI-GGUF-Loader](https://github.com/ChrisColeTech/ComfyUI-GGUF-Loader)):
- UNet family: [UnetLoaderGGUFMultiGPU](web/docs/UnetLoaderGGUFMultiGPU.md) / [UnetLoaderGGUFDisTorch2MultiGPU](web/docs/UnetLoaderGGUFDisTorch2MultiGPU.md)
- UNet Advanced bundles: [UnetLoaderGGUFAdvancedMultiGPU](web/docs/UnetLoaderGGUFAdvancedMultiGPU.md) / [UnetLoaderGGUFAdvancedDisTorch2MultiGPU](web/docs/UnetLoaderGGUFAdvancedDisTorch2MultiGPU.md)
- CLIP family: [CLIPLoaderGGUFMultiGPU](web/docs/CLIPLoaderGGUFMultiGPU.md) / [CLIPLoaderGGUFDisTorch2MultiGPU](web/docs/CLIPLoaderGGUFDisTorch2MultiGPU.md)
@@ -141,7 +143,7 @@ All MultiGPU nodes available for your install can be found in the "multigpu" cat
Detailed technical documentation is available for all **automatically-detected core MultiGPU and DisTorch2 nodes**, covering 70+ documented nodes with comprehensive parameter details, output specifications, and DisTorch2 allocation guidance where applicable.
-- **To access documentation**: Click on any core MultiGPU or DisTorch2 node in ComfyUI and select "Help" (question mark inside a circle) from the resultant menu
+- **To access documentation**: Click on any core MultiGPU or DisTorch2 node in ComfyUI and select "Help" (question mark inside a circle) from the resultant menu
- **Coverage**: All standard ComfyUI loader nodes (UNet, VAE, Checkpoints, CLIP, ControlNet, Diffusers) plus popular GGUF loader variants
- **Contents**: Input parameters with data types and descriptions, output specifications, usage examples, and DisTorch2 distributed loading explanations with allocation modes and strategies
- **Note**: Documentation covers core ComfyUI-MultiGPU functionality only. Third-party custom node integrations (WanVideoWrapper, Florence2, etc.) have their own separate documentation.
@@ -290,7 +292,7 @@ All workflows have been tested on a 2x 3090 + 1060ti linux setup, a 4070 win 11

Florence2 Detailed Caption to FLUX Pipeline
-
+
diff --git a/__init__.py b/__init__.py
index 2d00d58..c7a0377 100644
--- a/__init__.py
+++ b/__init__.py
@@ -791,7 +791,7 @@ def register_and_count(module_names, node_map):
"TripleCLIPLoaderGGUFMultiGPU": override_class_clip_no_device(TripleCLIPLoaderGGUF),
"QuadrupleCLIPLoaderGGUFMultiGPU": override_class_clip_no_device(QuadrupleCLIPLoaderGGUF)
}
-register_and_count(["ComfyUI-GGUF", "comfyui-gguf"], gguf_nodes)
+register_and_count(["ComfyUI-GGUF", "ComfyUI-GGUF-Loader","comfyui-gguf-loader", "comfyui-gguf"], gguf_nodes)
pulid_nodes = {
"PulidModelLoaderMultiGPU": override_class(PulidModelLoader),